
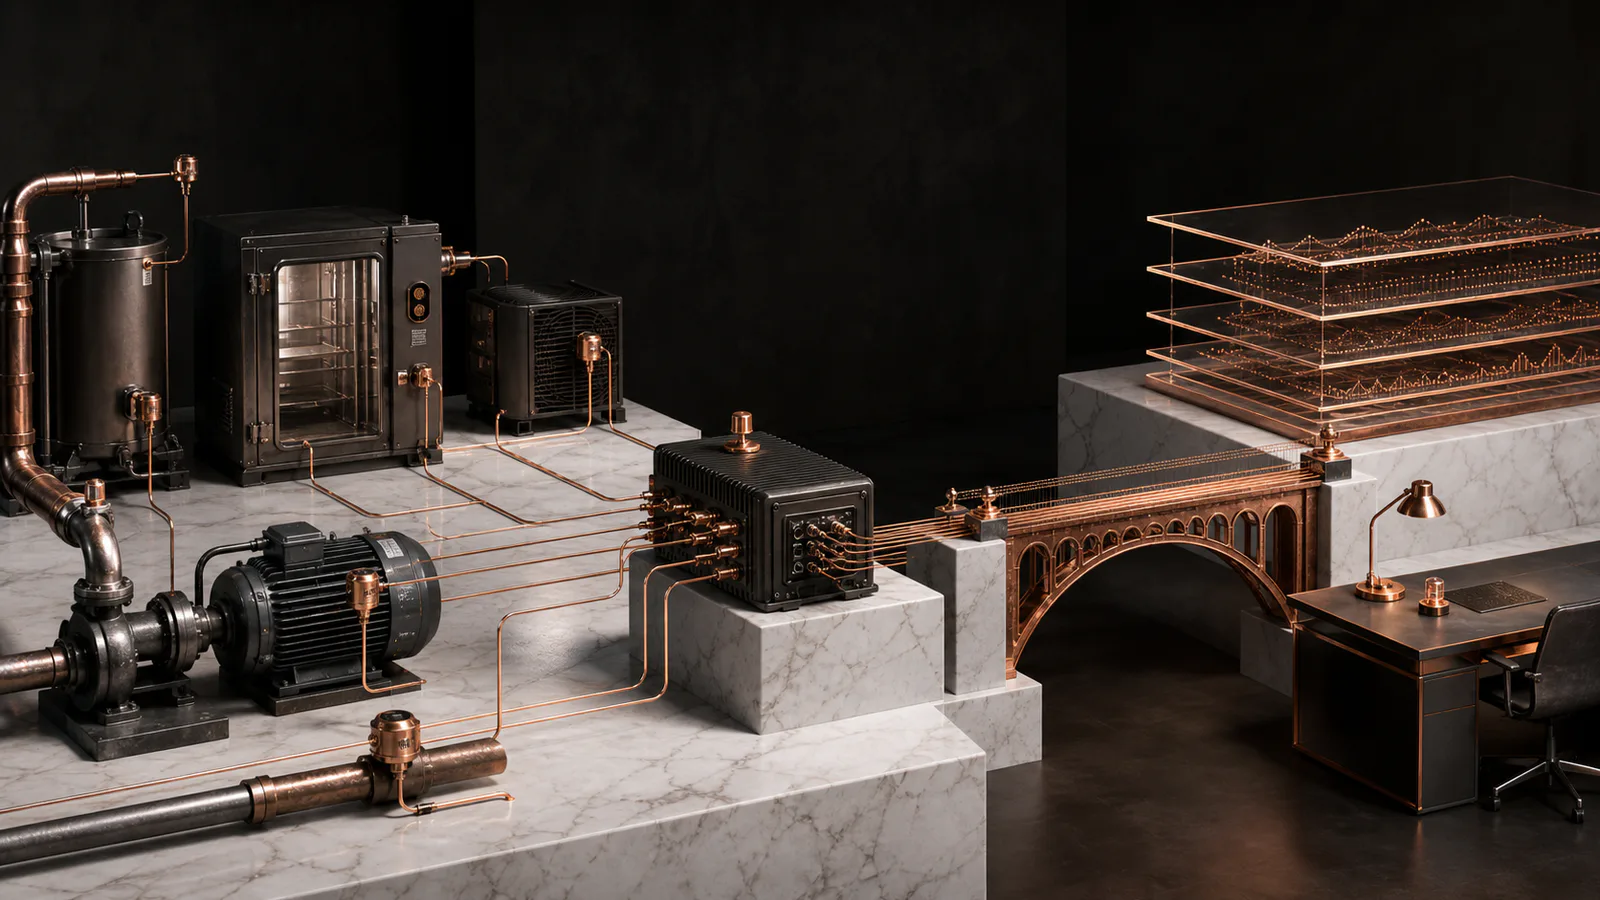
- Sensor or controller point
- Timestamped record and local buffer
- Authenticated connection
- Trend or alert with data freshness
- Maintenance review and response
Choose the platform around the measurement
Start with the signal, the useful warning window, the installation and who will respond. An ESP32 module can be a good fit for an unattended measurement node; an existing controller, industrial remote I/O or a supported gateway may be a better fit when it already exposes reliable data or the site requires a particular interface, approval or service model.
- ESP32-C3: straightforward connected node
- Single-core RISC-V with 2.4 GHz Wi-Fi and Bluetooth LE. Consider it for slow temperature, contact or pulse measurements and periodic reporting. Check usable pins, memory headroom during reconnect and update, and power at the complete node, including the sensor and regulator.
- ESP32-S3: local signal processing
- Dual-core Xtensa LX7, 2.4 GHz Wi-Fi, Bluetooth LE and vector instructions. Consider it when sampling and processing vibration or acoustic windows locally. Module memory options differ; measure sample loss, processing time and peak memory while communications are active. A faster core cannot recover information lost at the sensor or mount.
- ESP32-C6: a site with an established radio plan
- 2.4 GHz Wi-Fi 6, Bluetooth LE and IEEE 802.15.4 for Thread or Zigbee designs. Choose the network based on installed coverage and gateway ownership. A radio feature does not provide a border router, an approved network path or a battery-life result.
- ESP32-P4: local display or imaging
- Consider it when a camera or display interface is central to the job, such as local gauge-image processing. Wireless connectivity needs a separate component. That extra integration is usually unnecessary for a temperature or pulse logger.
- Nordic nRF52840, STM32G4 and Raspberry Pi Pico 2 W
- Compare Nordic for a Bluetooth LE node reporting through a separate gateway, STM32G4 for a mixed-signal design where analog acquisition and timing lead the decision, and Pico 2 W for an RP2350-based prototype that benefits from programmable I/O. Compare the complete assembly, firmware support, wired interfaces, supply and recovery plan before choosing any board.
Make the signal trustworthy before adding an alert
Instrument the condition, not just the nearest available point
Document the sensor location, range, units, response time and relationship to the equipment state. A temperature probe near a door measures something different from a probe in the return-air stream. A vibration trend also depends on mount, axis, speed and load. Establish a reference and record the calibration or comparison method before accepting the trend.
Match the electrical interface to the site
Short internal digital connections, field current loops, pulse outputs and an existing serial bus call for different interfaces. A 4–20 mA signal needs a suitable receiver with the required protection and isolation; an RS-485 or CAN bus needs a suitable transceiver and a verified connection plan. Neither is a direct GPIO connection. Keep analog filtering, shielding, grounding and isolation appropriate to the installation. For an analog input, use the chip's ADC calibration guidance and verify the whole measurement chain against a reference. Use a dedicated front end if the required accuracy, noise floor or sampling bandwidth calls for one.
Preserve enough evidence for the decision
Choose the sampling and filtering strategy for the shortest event of interest. Fast waveform acquisition needs anti-alias filtering before sampling or decimation and a known sample clock. For slow trends, preserve the timestamp, unit, quality and relevant operating state. Record the sensor and configuration version. An average should not erase an excursion, and a stale value should not pass as a current reading.
Related engineering notes: electrical noise in analog signals and downsampling without losing diagnostic evidence.
Design firmware for interruptions and service visits
Keep acquisition independent of delivery
Acquire and validate locally, then pass records to a bounded upload queue. Attach device and channel identity, event time or an explicit unsynchronized-clock flag, sequence, units and quality. Retain event time on replay and record server receipt time separately. Use a persistent record identity to handle duplicate deliveries after reconnect or restart. Define queue capacity, write endurance and what happens when storage fills; surface data loss instead of silently overwriting evidence.
Keep the fleet recoverable
Give each node its own credentials and restrict it to the data it may publish. Use authenticated transport, document how to replace or revoke a node, and test operation when credentials expire or the network disappears. Decide what should happen after a brownout, watchdog reset or interrupted configuration write. Where the device supports it, configure signed firmware, secure boot and flash protection as part of a documented provisioning and service process.
Use a known-good update path: stage a signed image, test it on a small group, and confirm startup and acquisition before marking it good. ESP-IDF's application OTA and rollback guidance explains the partition and validation requirements. Test loss of power during update and verify a real recovery route; application rollback does not make every partition update power safe.
Check the installed assembly, not just the bench prototype
- Power: verify the full node during startup, radio transmit, reconnection, sampling and sleep. Include sensor, regulator, storage and battery behavior at expected temperatures.
- Mounting and environment: check cable strain, connectors, condensation, washdown, vibration and access for replacement. A module's approval or a bare enclosure rating does not establish compliance for the finished assembly or installation.
- Connectivity: survey message delivery at the intended mounting point with doors and machinery in representative states. Agree how long the site can be offline, how it reports loss of visibility and who handles a prolonged outage.
- Commissioning: compare readings to a reference, force a known event and a missing reading, interrupt power and connectivity, replay data, and confirm the named responder can distinguish an equipment issue from a device or network issue.
- Authority: keep the monitoring pilot read-only. Existing local controls, interlocks and safety procedures remain in authority. Electrical work, hazardous locations and regulated installations require the appropriate site and specialist review.
Plan the field check with the wireless survey guide, battery budget guide, enclosure guide and hazardous-location review guide.
20 equipment monitoring applications to evaluate
These are design possibilities, not completed engagements. Where a broader application involves control or certification, the example here is limited to the monitoring portion.
Rotating equipment and production
- Motor bearing vibration: capture repeatable waveform windows and compare vibration features at similar speeds and loads. Route an unusual trend to inspection.
- Lubricant condition: trend temperature alongside optical or dielectric readings. Compare against sampled fluid before treating the signal as a contamination diagnosis.
- Motor current signatures: use authorized, isolated acquisition with synchronized phase data to compare operation under known loads. Qualified personnel own the electrical work and diagnosis.
- Compressed-air leak screening: record local ultrasonic features and background conditions; use an inspection to confirm a suspected leak and its location.
- Conveyor idler checks: compare vibration or acoustic windows while the belt is running under comparable conditions. Identify the roller and inspection owner.
- Chiller or heat exchanger performance: trend paired temperatures with flow and load context. An approach-temperature change is a reason to investigate, not a standalone fouling diagnosis.
- Dust collector filter condition: trend differential pressure with fan state; flag sensor loss separately. Leave pulse cleaning and protective controls untouched.
Facilities, cold storage and utilities
- Walk-in cooler excursions: log air temperature and door state, distinguish a sustained excursion from a door cycle, and retain missing-data flags. Follow the site's existing food-safety procedures.
- Water tank level: compare readings with known levels, test for dead zones or foaming, and route a persistent change to the operator. Existing overflow and pump protection remain independent.
- Equipment-room water leaks: map sensing rope to a zone and distinguish wet, disconnected and unreported states. Record who checks the location.
- Indoor air quality: log selected pollutants or conditions at a documented placement, and check drift and ventilation context before interpreting trends.
- Backup generator visibility: read permitted run status, alarms and fuel level from existing outputs. Verify exercise events appear without issuing transfer or start commands.
- Electrical consumption: retrieve data from an approved submeter to identify changes in usage. Keep billing and protective functions with their authorized systems.
- Solar inverter telemetry: read documented status and generation values, preserving offline or stale state. Leave curtailment and interconnection functions in the inverter system.
Retrofits, agriculture and service equipment
- Legacy PLC or CNC visibility: export a small, approved register set with explicit scaling and quality. Validate polling impact and deny all control writes.
- Soil moisture profiles: compare moisture trends at several documented depths and check sensor response in local soil before recommending an irrigation review.
- Greenhouse climate: measure temperature and humidity where crops are grown; label any calculated vapor-pressure deficit with its assumptions. Local climate controls stay independent.
- Orchard microclimate: compare conditions at two heights or locations to inform a frost review. Existing response procedures remain primary when a node is unavailable.
- Commercial ice machine cycles: count harvest cycles and track bin-level status to give service staff a better starting point; validate indicators against observed operation.
- Water filtration service checks: compare readings upstream and downstream where supported and log service intervals. Conductivity and lamp status alone do not establish water safety.
Three worked designs: what to build and what to prove
The figures below are illustrative design inputs, not field measurements or promised performance. Set acceptance limits with the site before installation.
1. Capture evidence from one motor without streaming continuously
Signal and node: shortlist an ESP32-S3 with an SPI accelerometer such as the ADXL355 if its measurement range and bandwidth suit the target feature. Use a consistent mount and axis; record operating speed or another reliable state marker. Choose a different sensor if the fault band is outside the usable measurement chain.
Illustrative sizing: at 2,000 samples per second, a 1,024-sample window lasts 0.512 seconds and gives roughly 1.95 Hz spacing between FFT bins. Three axes packed at three bytes per sample need 9,216 bytes per raw window, before buffers and record overhead. Bin spacing does not establish useful resolution or diagnostic accuracy. Agree the passband and use filtering and a suitable window before comparing spectra.
Test: compare repeated runs and known speed changes to a reference instrument. Exercise clipped readings, missed samples and reconnection under load. Publish condition features and retain selected windows for human review. If speed or load cannot be distinguished, present that uncertainty and withhold a fault classification.
2. Keep a cooler's excursion history through a network outage
Signal and node: use a suitable temperature probe, a door contact and an ESP32-C3 candidate on an approved network. Compare the probe to a reference at its installed point. Keep separate states for threshold excursion, open door, failed probe and missing telemetry. Set duration and recovery rules with the operator; the logger does not replace required records or procedures.
Illustrative sizing: one combined record per minute gives 1,440 records in 24 hours. At an assumed 64 bytes per stored record, the payload alone is 92,160 bytes. Budget more for indices, integrity checks, flash management and bursts. Agree what happens when the outage exceeds capacity and how the operator sees the gap.
Test: simulate an excursion, disconnect the probe and interrupt both network and power. Confirm that replay preserves event order and shows any gaps without duplicating the alert. Verify that a designated person receives, acknowledges and can investigate the test notification. This checks the monitoring chain; it does not certify a cold-chain process.
3. Add read-only telemetry to a legacy machine
Signal and node: ask the machine owner for the approved register map and bus topology. Prefer a supported gateway or an existing export if the bus already has an active master. Where a new reader is approved, compare an isolated industrial gateway with an ESP32 module and isolated RS-485 interface; choose for serviceability and the site's network policy. Permit only documented reads, never writes or arbitrary remote register commands.
Illustrative sizing: eight 16-bit registers contain 16 data bytes before framing. With a five-second polling interval, the maximum nominal rate is 12 polls per minute before timeouts or backoff. That is not a bus-loading estimate: measure request and response framing, turnaround, existing traffic and worst-case timeouts before setting an approved rate.
Test: compare each exported value against the local display or an approved reference. Check units, sign, scaling and multi-register ordering where applicable. Test a timeout, invalid data and loss of upstream connectivity. Verify the machine operates unchanged and that a disconnected reader produces a stale or unavailable state rather than a false machine fault.