
A business can keep useful work moving overnight without allowing software to make every decision while staff sleep. It can reconcile approved records, prepare the next day's exception briefs, and complete narrowly authorized routines. The difficult part is not persuading an agent to keep trying. It is ensuring that unfinished work remains understandable and recoverable.
Continuous execution needs durable state, controlled actions, sensible resource limits, and a person responsible for the situations that cannot be resolved automatically.
Distinguish unattended from unrestricted
An unattended workflow operates without a person guiding every step in real time. It does not need unlimited discretion. A scheduled report can run autonomously while remaining read-only. A replenishment process can prepare a proposal without issuing a purchase order.
Define the useful accepted state for each task. A prepared proposal, a reconciled record, and a completed external action should have different statuses. Staff should not need to infer what happened from the assistant's final message.
Availability is also a dependency question. A model endpoint running overnight does not make the inventory system, identity service, or support team continuously available.
An illustrative overnight replenishment run
Imagine a distributor reviewing stock each night to prepare purchasing proposals. The workflow reads approved inventory, open orders, and supplier records. Conventional rules identify eligible products and prevent duplicate proposals for the same demand.
AI can help summarize unusual demand or supplier notes, clearly separating observed records from interpretation. The authorized buyer receives a morning proposal with evidence, quantities, assumptions, and unresolved exceptions. The system does not independently commit spending outside the approved operating boundary.
If a stock feed is stale, the affected proposal is held. If the supplier service is unavailable, the workflow records the missing evidence and schedules an appropriate later check within its limits. It does not invent a lead time to produce a complete report.
The buyer can see what was prepared, what was held, and why. That visibility is part of the overnight result, not an optional monitoring feature.
Preserve state across interruption
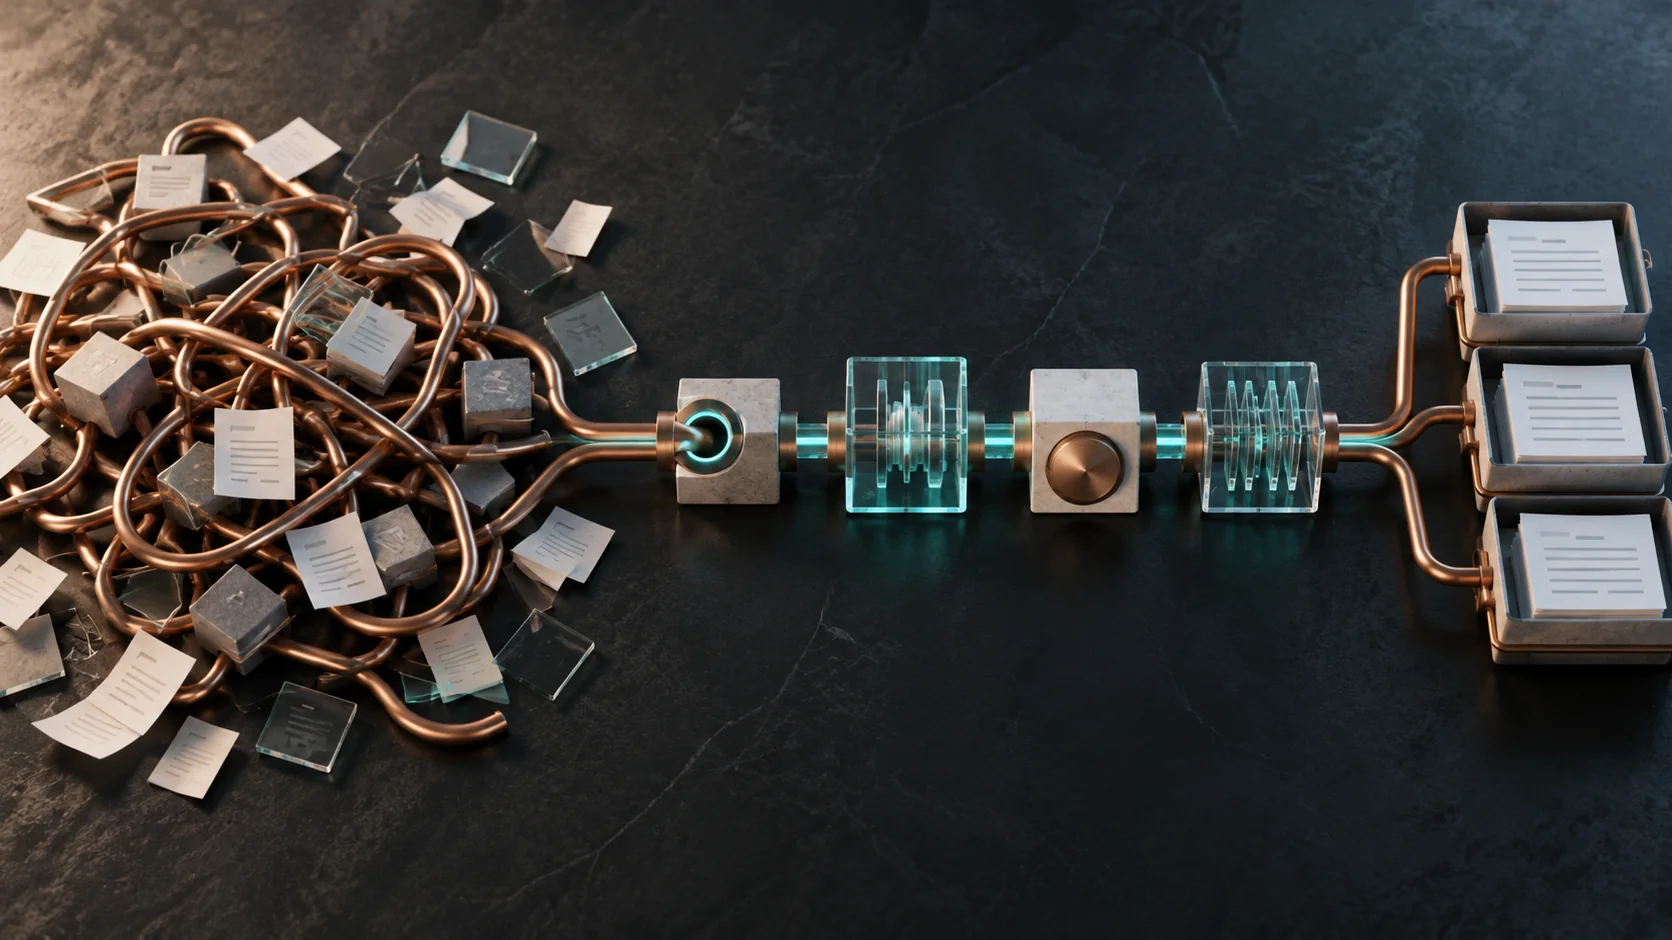
A process can stop because of a machine restart, provider outage, expired credential, or resource limit. Store the task's current state, source versions, completed steps, and pending actions in a dependable operational record.
Temporal's durable-execution documentation illustrates one implementation approach using recorded workflow history. Other architectures can serve the need. The design choice should follow the workload rather than a requirement to adopt a particular platform.
Durable orchestration does not automatically make an external transaction exactly-once. Recovering the workflow and determining what a remote service actually did are related but separate problems.
Make retries safe
Suppose a system sends an authorized request and loses the response. Retrying may be correct if the first request failed. It may be harmful if the first request succeeded and a second execution creates a duplicate commitment.
Use a stable operation identifier and a downstream contract that can recognize repeated intent. Check the authoritative result before deciding whether another action is necessary. Amazon's idempotent API guidance explains why request identity, stored state, and retention rules matter.
A request with the same parameters can sometimes be a new intentional action rather than a retry. The system must distinguish those cases explicitly. “We use an idempotency key” is not enough evidence that every connected provider handles duplicates safely.
Define limits and escalation
Set a maximum duration, retry policy, resource budget, and allowed actions for each run. A failure should move the task into a visible state with an owner, not into an endless loop or a silent disappearance.
Some work should wait. A supplier substitution, unusual financial commitment, unclear customer instruction, or safety-sensitive decision may require a person. Holding those cases is part of correct operation, not evidence that the workflow lacks ambition.
Decide which alerts need immediate attention and which belong in the morning queue. An overnight system that constantly wakes staff for low-value notifications may create more disruption than it removes.
Distinguish a paused run from a failed one. A budget ceiling, missing approval, or planned dependency outage may intentionally hold work without requiring emergency recovery. Record the reason, the condition needed to resume, and the owner. Otherwise staff may either restart a correctly held process or overlook a genuinely failed action because both appear as the same generic warning.
Give the morning review a useful shape
Present accepted completions, pending work, exceptions, costs, and any actions requiring reconciliation. Link each item to its source evidence and authoritative result. Show the oldest unresolved work so it cannot be buried by a large volume of successful routine tasks.
Periodically test outages, duplicate events, stale data, and the emergency stop. Confirm that staff can resume the process without losing records or repeating external actions.
The useful promise is not that a business can operate without people. It is that well-defined work can continue responsibly between human decisions, leaving the next person with a clear account of what happened and what needs attention.
Sources & further reading
Primary references checked October 18, 2026. Examples are illustrative, not reported client outcomes.
- Temporal: Understanding durable executionOfficial implementation documentation on recorded workflow history and recovery; not a guarantee of business success.
- Amazon Builders' Library: Making retries safe with idempotent APIsExplains request identity, duplicate effects, and the limits of retry guarantees.